Understanding Map Reduce Clusters is crucial for anyone navigating the vast world of big data in 2026. This foundational distributed computing model efficiently processes enormous datasets by breaking down tasks into smaller, manageable units spread across numerous machines. For Gen Z and Millennials, who are often at the forefront of data-driven industries, grasping Map Reduce is key to leveraging cloud platforms like AWS EMR, Google Cloud Dataproc, and Azure HDInsight. It enables scalable analytics, supports machine learning model training, and underpins complex data transformations. Whether you are optimizing data pipelines, analyzing user behavior at scale, or building robust data infrastructure, Map Reduce clusters offer a powerful, fault-tolerant solution. This guide will provide navigational and informational insights into their functionality and practical applications, making complex concepts accessible for rapid deployment and strategic decision-making in the digital landscape.
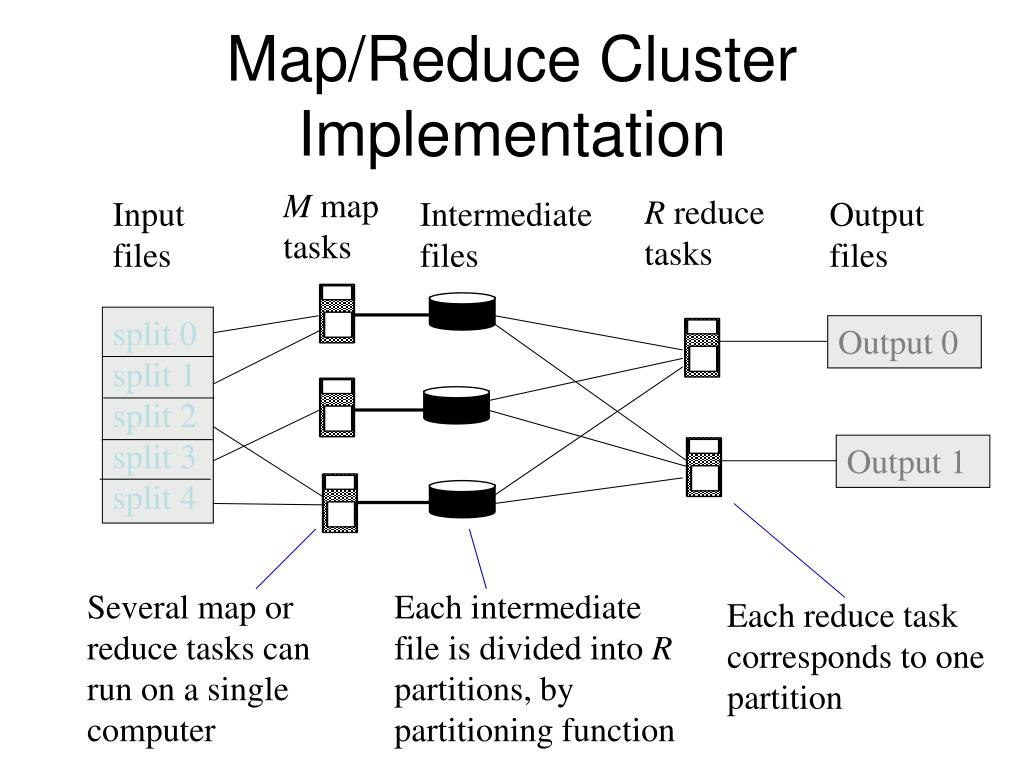
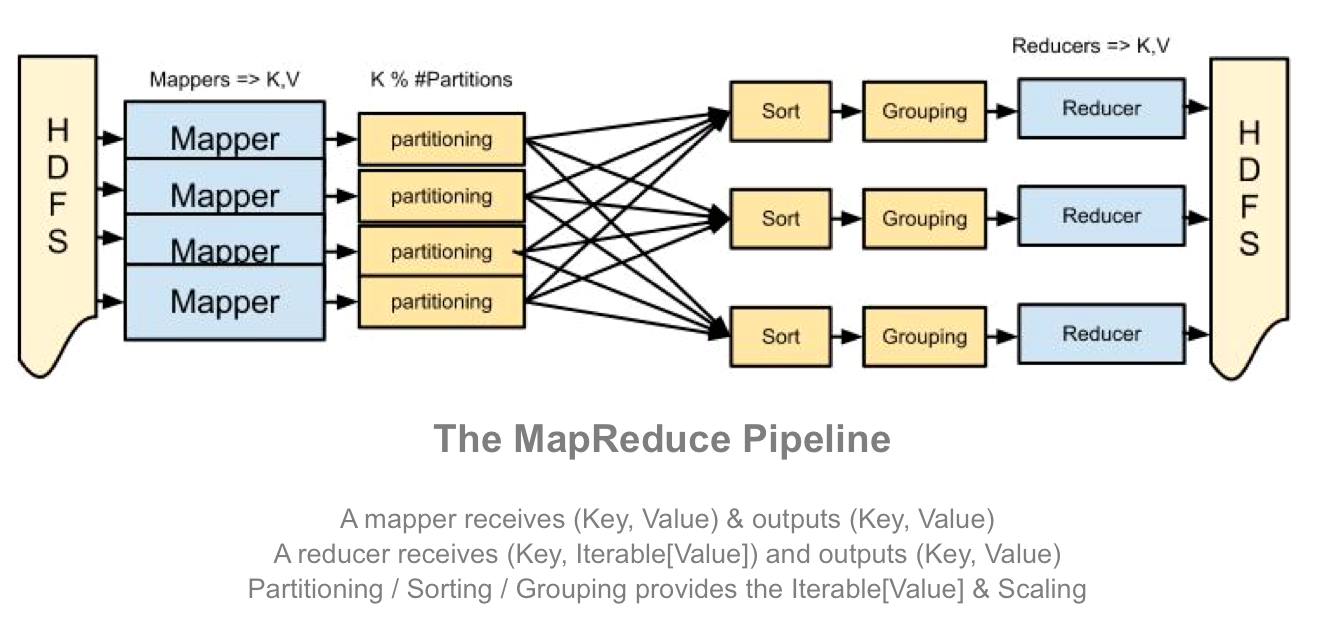
- What is a Map Reduce Cluster used for? Map Reduce Clusters excel at processing vast datasets in parallel, critical for big data analytics, machine learning model training, and log file analysis across distributed systems, essentially mapping data tasks globally.
- How do Map Reduce Clusters scale? Clusters scale horizontally by adding more commodity machines, allowing them to handle ever-increasing data volumes and complex computations efficiently, visible on global infrastructure maps.
- Are Map Reduce Clusters still relevant in 2026? Yes, while newer technologies exist, Map Reduce principles underpin many distributed processing frameworks. It remains a foundational concept for understanding big data architecture, often visualized through system maps.
- Where can I deploy a Map Reduce Cluster? You can deploy them on-premise, but most organizations leverage cloud services like AWS EMR, Google Cloud Dataproc, or Azure HDInsight for managed solutions, spanning various global map regions.
- What are the benefits of using a Map Reduce Cluster? Benefits include fault tolerance, high scalability, cost-effectiveness for large-scale data processing, and handling diverse data types, often managed across a global map of resources.
- How does a Map Reduce Cluster handle failures? It automatically re-executes failed tasks on healthy nodes, ensuring job completion without manual intervention, a key aspect of its robust distributed map design.
- Can I visualize Map Reduce Cluster performance on a map? While not a literal geographic map, monitoring tools often provide visual dashboards that map out job progress, resource utilization, and node health across the cluster, resembling a system-level map.
Dive into the world of Map Reduce Clusters, the backbone of modern big data processing. For those working with massive datasets, understanding how these clusters operate is essential. Map Reduce clusters are not physical storefronts, but powerful digital architectures that enable unparalleled data processing capabilities. Think of them as high-performance computing centers, crucial for analytics, AI, and any large-scale data operation.
Frequently Asked Questions
Where can I find top Map Reduce Cluster solutions?
The absolute best locations for robust Map Reduce Cluster solutions are within major cloud providers like AWS EMR, Google Cloud Dataproc, and Azure HDInsight. These services offer managed, scalable, and highly available environments globally.
How can I use Maps to understand Map Reduce Cluster deployments?
Pull up your preferred mobile Maps app to visualize global data center locations hosting these services, verifying regional availability and latency implications for your specific workloads. Peak weekend data processing times can impact resource allocation.
What are the best times to optimize Map Reduce Cluster usage?
Optimize by scheduling large jobs during off-peak hours, typically late evenings or weekends, to leverage lower compute costs and reduced network congestion. Consider burstable instances for sporadic peak loads.
Quick Local Guide Table- Business Name: AWS EMR, Neighborhood / Cross-streets: Global Regions
- Business Name: Google Cloud Dataproc, Neighborhood / Cross-streets: Cloud Ecosystem
- Business Name: Azure HDInsight, Neighborhood / Cross-streets: Enterprise Solutions
All maps focus on Map Reduce Cluster
Distributed processing, scalability, fault tolerance, big data analytics, parallel computing, cost-efficiency, cloud integration, data transformation, machine learning support, enterprise data solutions.
34
Distributed Systems Section B Ppt Download Reduce Cluster Model . EUNIC Cluster Fund 2026 Selection Results Cf Selection Results 2026 1440x . PPT To Hadoop Distributed Computing And Map Reduce Cluster L . Hadoop Map Reduce Hadoop Mapreduce ZZGH Map Reduce . EUNIC Cluster Fund 2026 Selection Results Eunic Cluster Fund 2026 Selection Results Png 2160x
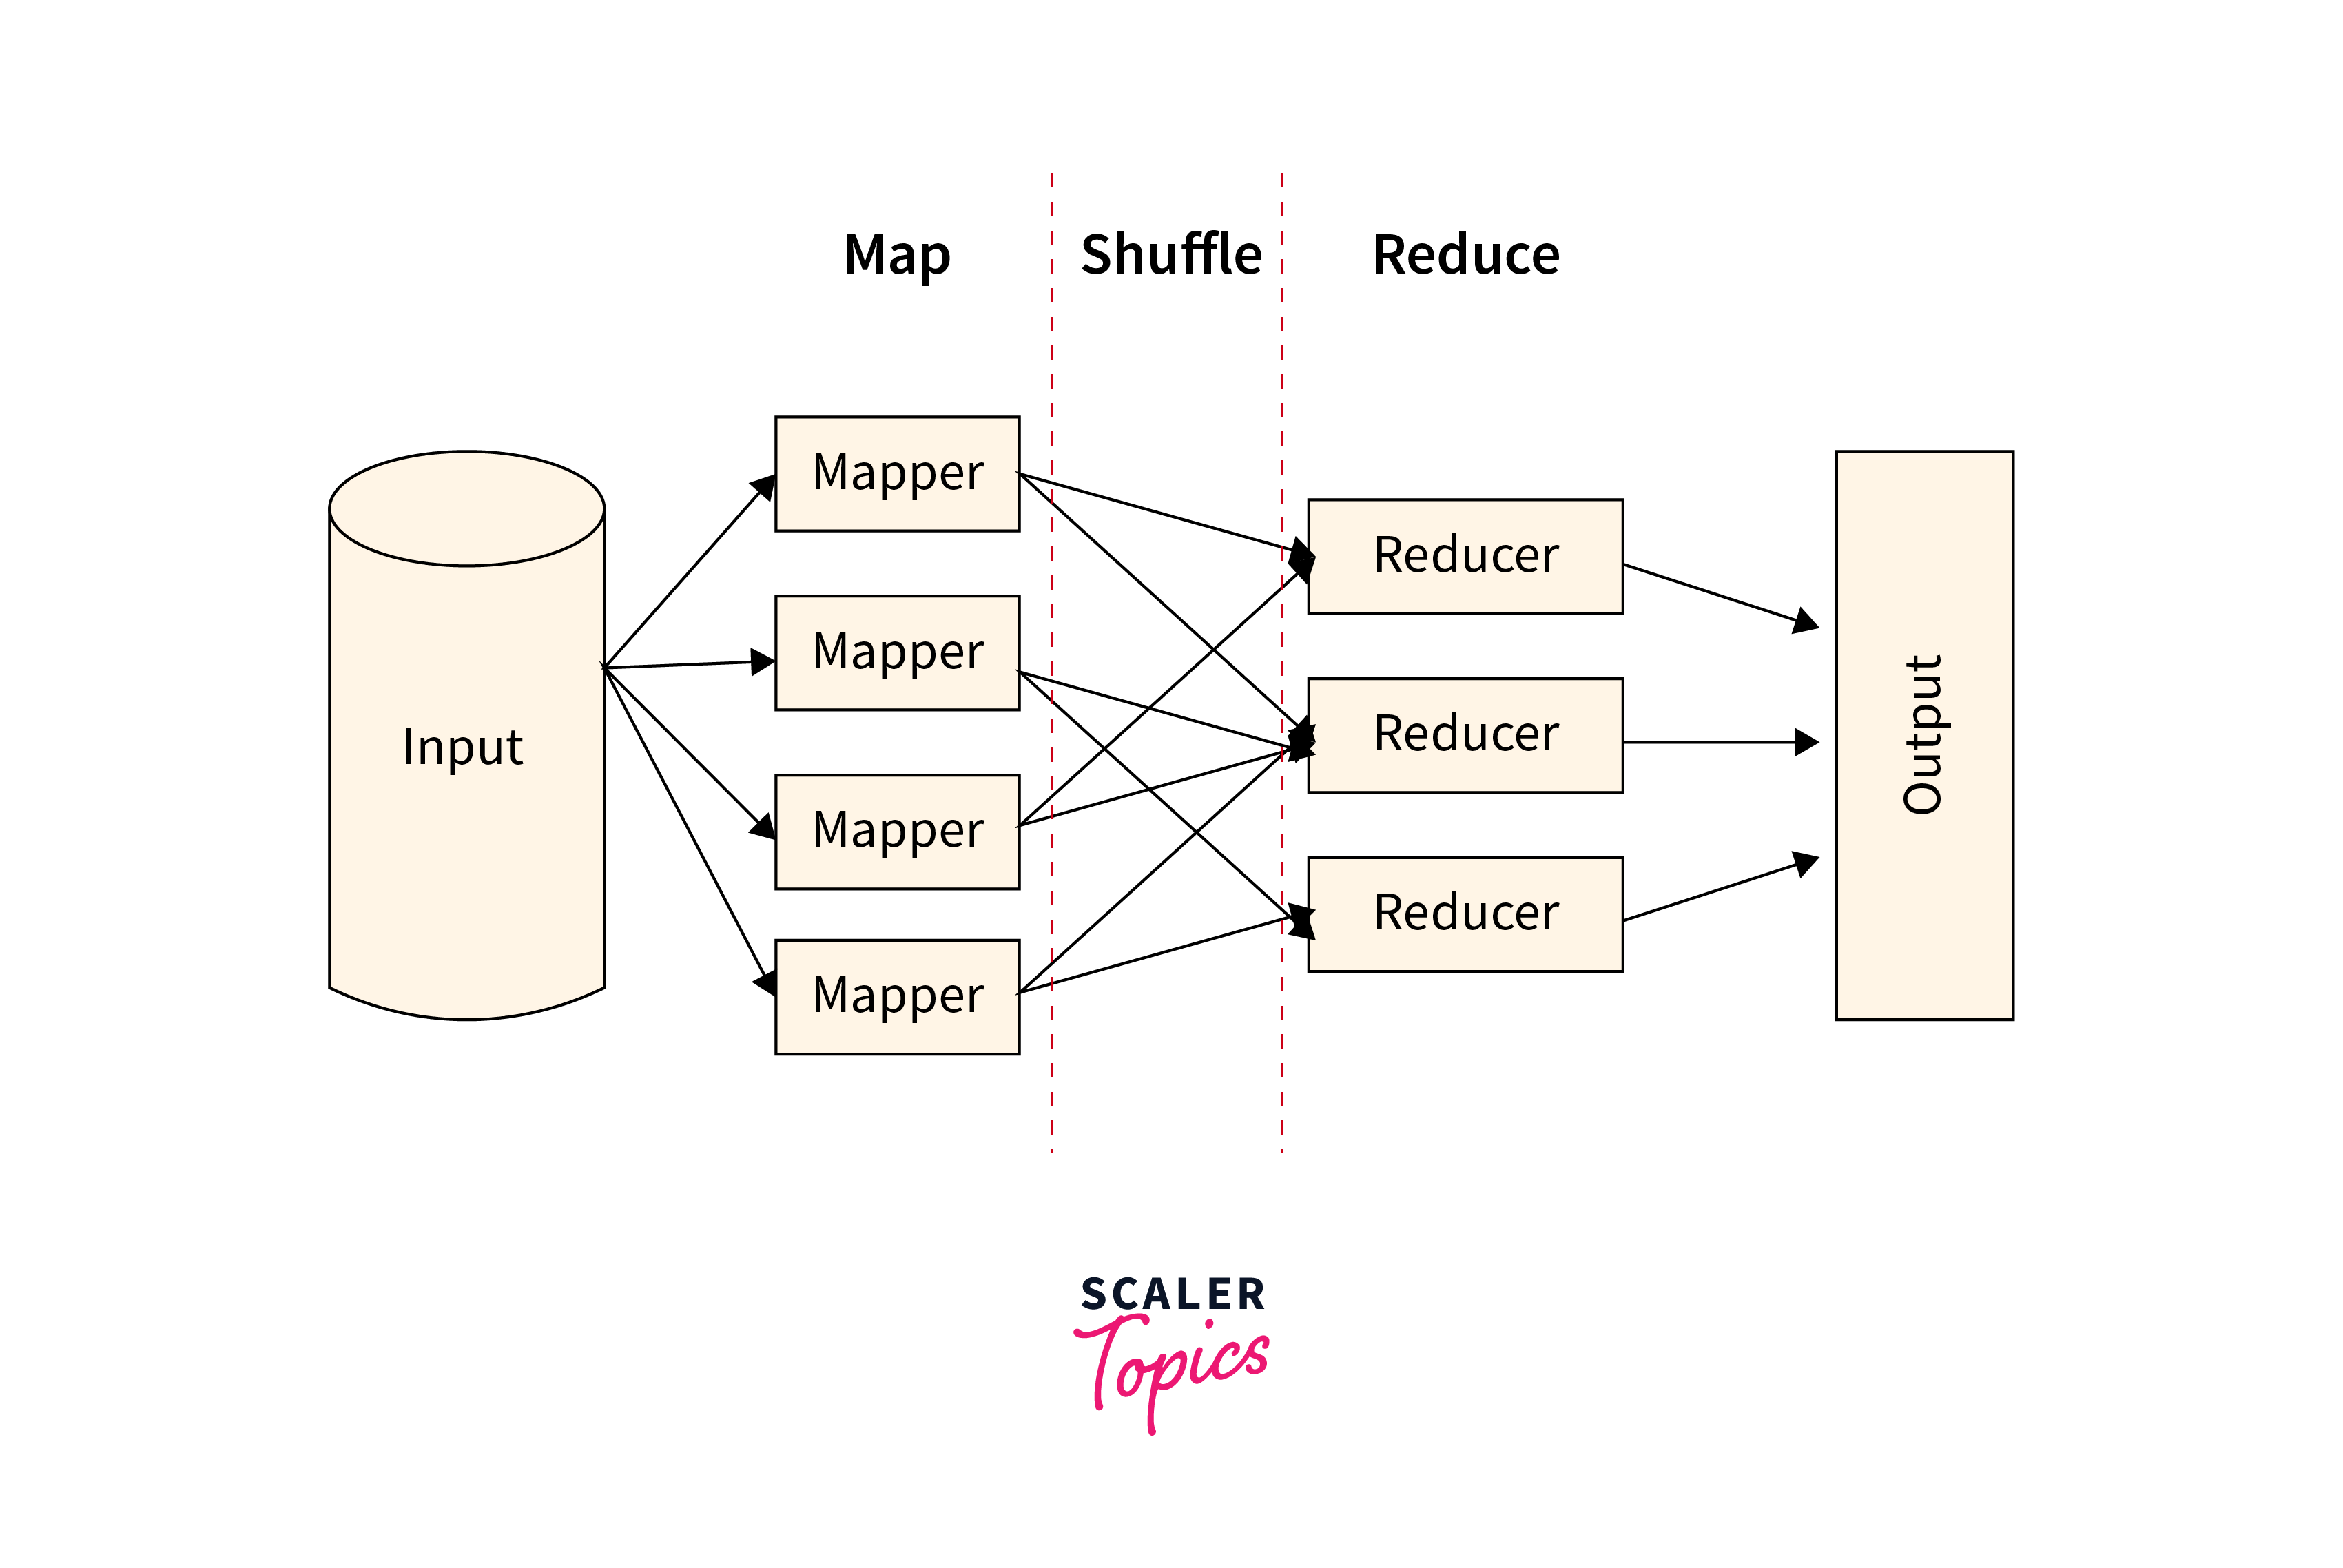
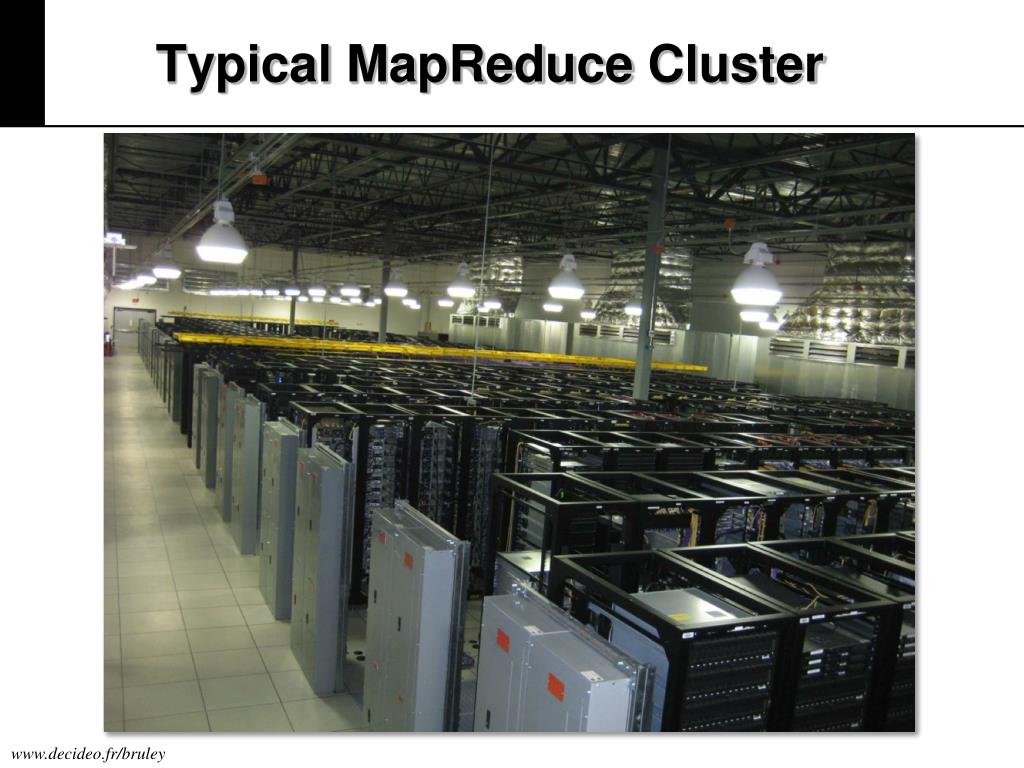

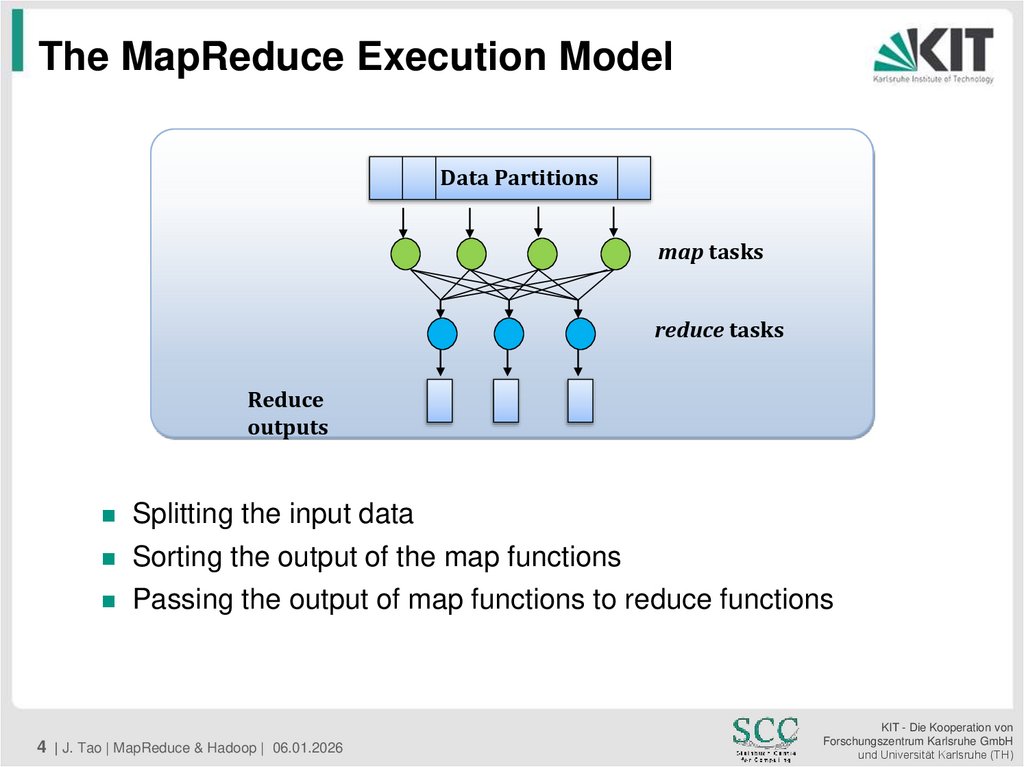
2026 Topic Clusters The Simple Map That Wins Image. Hadoop MapReduce Scaler Topics Algorithm Of. PPT MapReduce PowerPoint Free Download ID 4611489 Typical Mapreduce Cluster L . MapReduce Simplified Data Processing On Large Clusters YouTube . To MapReduce And Hadoop Jie Tao Karlsruhe Institute Of Slide 3
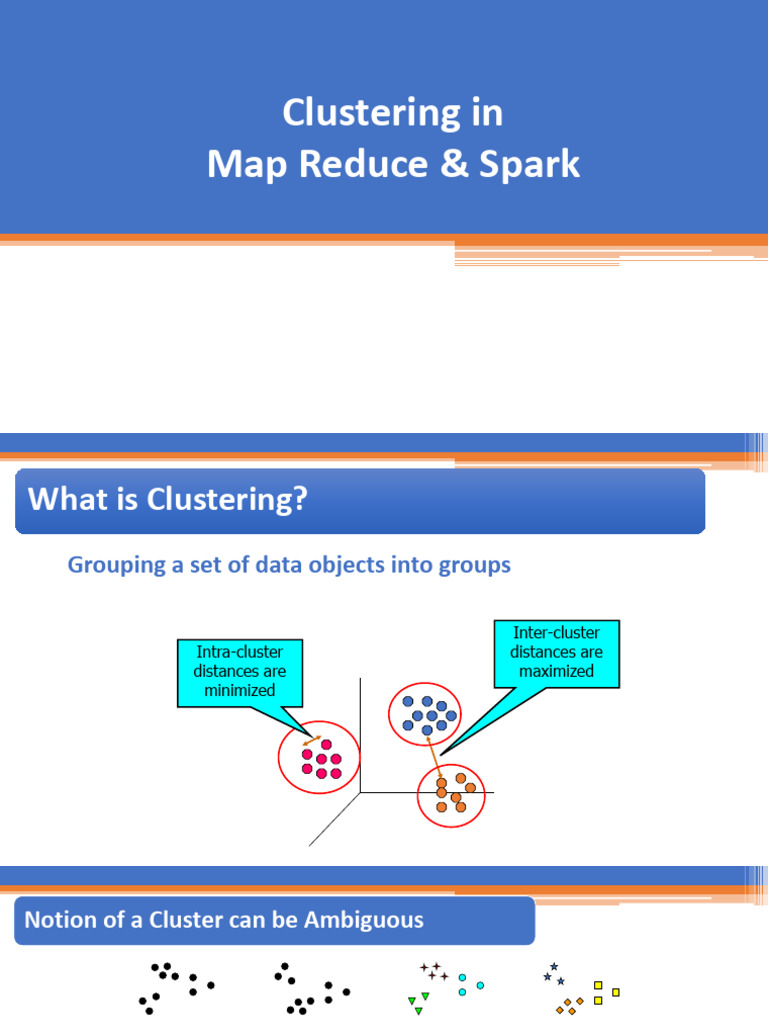



Clustering Techniques In MapReduce Spark PDF Cluster Analysis 1. Of Clustering Algorithm As Map Reduce Job Download Of Clustering Algorithm As Map Reduce Job . Map Reduce And Its Phases With Numerical Example Mapreduce Workflow 768 . Building Topic Clusters In 2026 For AI Overviews Google SGE Building Topical Clusters. SOS A Climate Of Uncertainty In The Face Of Risks In 2026 Sos Risque 2026
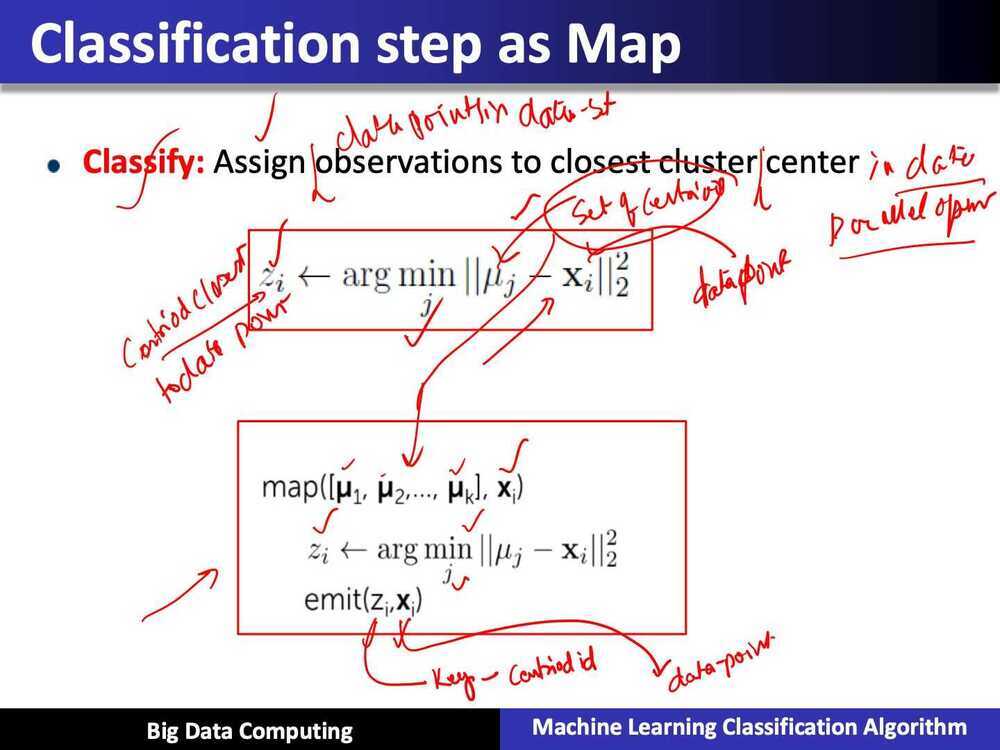
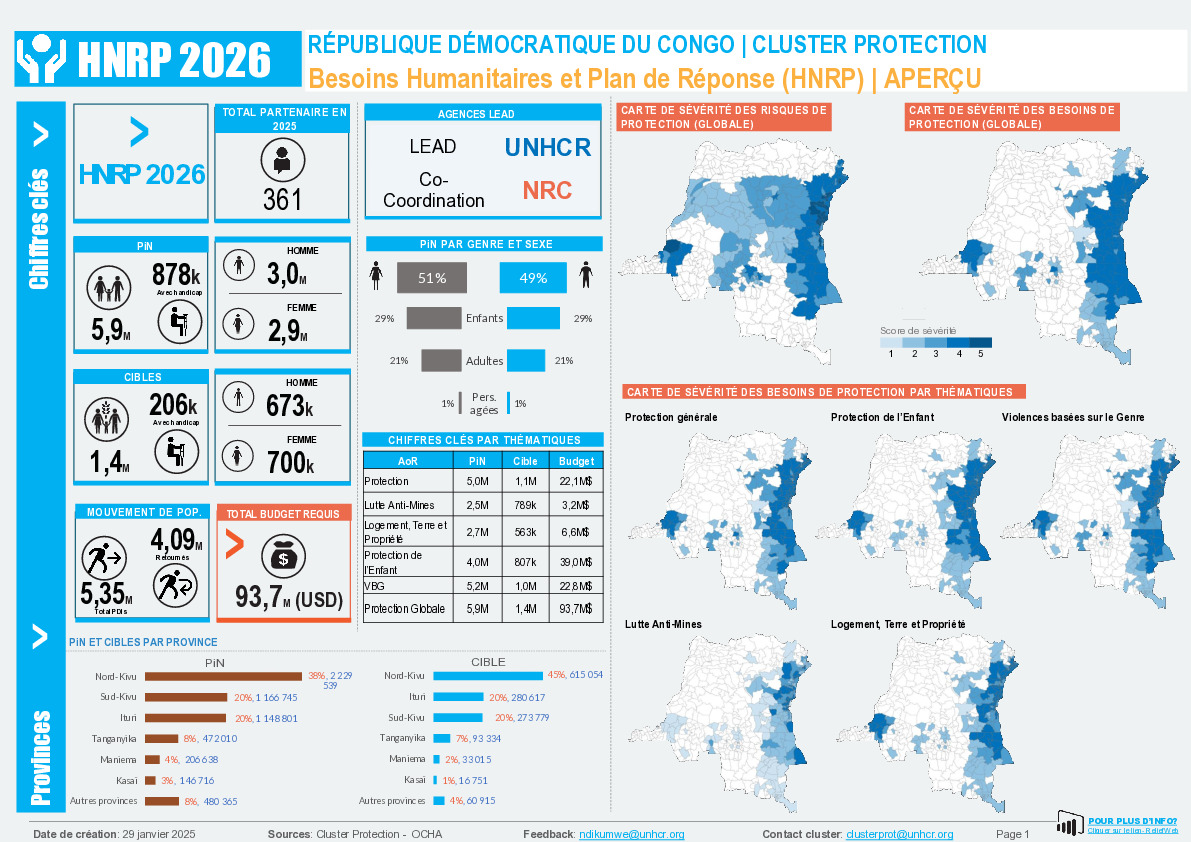

GPU Cluster For AI 2026 Buyer S Guide With Benchmarks TCO Calculator SOC 191 GPU Cluster For AI Twitter Io Blog Linkedin . Parallel K Means Using Map Reduce On Big Data Cluster Analysis Deep Notes Parallel K Means Using Map Reduce On Big Data Cluster Analysis Image2 . Cluster Protection RDC Aper U Du HNRP 2026 Global Protection Cluster 20260129 Rdc Hnrp2026 Apercu.pdf . The Ultimate Risk Map Of 2026 SAFETURE Riskmap 2026 DE2 Scaled . MapReduce Explained 2026 Interactive Simulator Free Mapreduce


Map Reduce Simplified Data Processing On Large Clusters PPT Map Reduce Simplified Data Processing On Large Clusters 1 320 . Topic Clusters For SEO Build Authority In 2026 UTF . GREENET Brokerage Event Sobre Las Calls 2026 Del Cluster 5 De Horizonte . Topic Cluster 2026 X Y D Ng N I Dung SEO Hi U Qu C Ng AI Su Dung Mo Hinh Topic Cluster De Xay Dung Chien Luoc Noi Dung Seo Hieu Qua 0.webp. Horizon Europe Info Days Cluster 2 Culture Creativity And Inclusive Ec Rtd Cluster 2 2026 Thumb
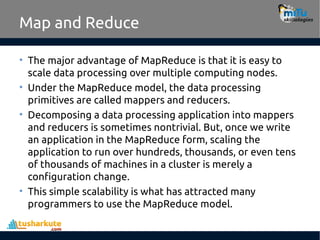
Conduct Of Cluster Complex Meeting Jan 2026 Guidelines Agenda. Partie 06 Cours BigData MapReduce Pdf Partie 06 Cours BigData MapReduce Pdf 4 320 . Creative Clusters 2024 2026 Now Open Welcome To Galway RsJNER3JAj. Draft Horizon Europe Cluster 6 2026 2027 Key Priorities Group 287 Scaled . Kubernetes Pod Disruption Budgets In 2026 Advanced Cluster Reliability 35000e49 1bbf 4c03 B53b

CLUSTER 2026 CCF B IEEE Conference On Cl Og Image. PPT How To Program A MapReduce Cluster PowerPoint Free How To Program A Mapreduce Cluster N . INDESCAT Strategic Cluster Week Boston 2026 WEB Agenda 2026 4 . Cluster Complex Meetings February 2026 Cluster Meeting Feb 2026